
Why Your Multi-Agent Setup Collapses the Moment You Add a Fifth Tool Server
Your agent worked fine with three MCP servers. Then you added a fourth and a fifth, and now it calls the wrong tool, retries three times, and burns through your token budget before lunch.
This is not a model problem. It is an architectural one. And there is a single layer that fixes most of it, one that has nothing to do with writing better prompts. I will show you exactly what that layer looks like after we cover why things break in the first place.
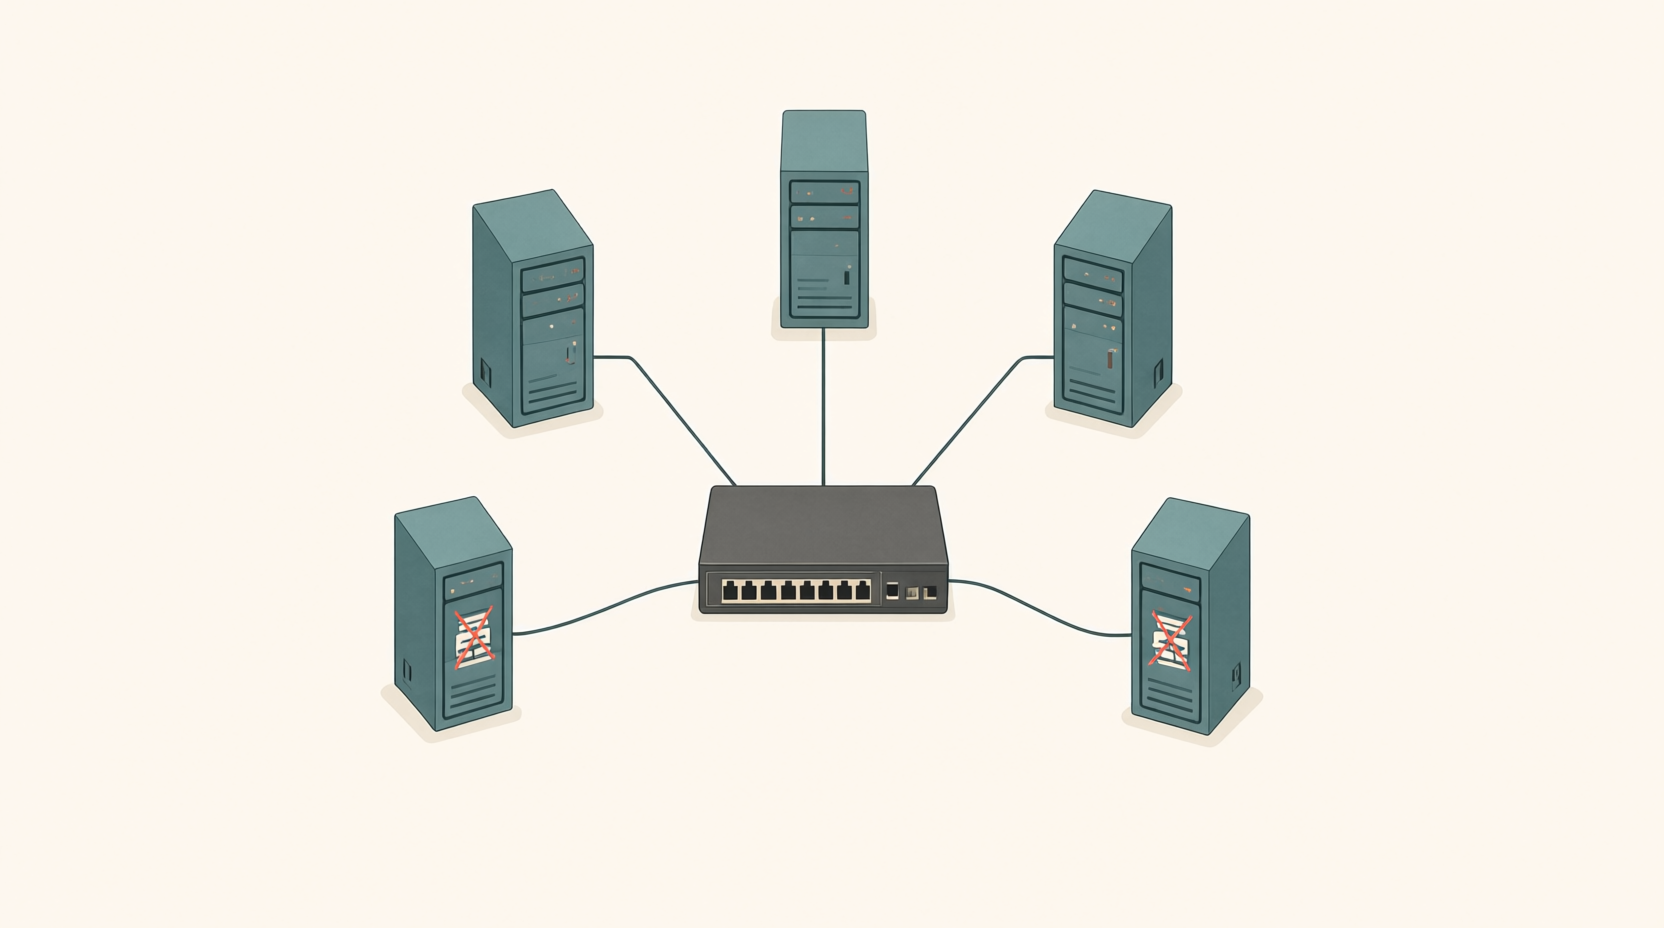
Here is the failure mode. Two servers both expose something like search or create_record. The agent sees overlapping definitions, guesses which one applies, and guesses wrong. Each wrong call triggers a retry. Each retry re-sends context. The cost compounds fast.
Tool-selection noise does not grow linearly with your server count. It grows faster. Keep servers narrow, roughly 3 to 5 active servers with 5 to 15 tools each, and the problem stays manageable. Blow past that and every added tool dilutes the signal for every existing one.
The MCP Gateway Pattern is not another agent wrapper. It is the missing layer between your agents and your tool servers.
What a Gateway Actually Does That a Prompt Cannot
You have probably tried the polite approach: "Please select the most appropriate tool." That is a suggestion, not a constraint. A gateway turns it into a rule.
Four responsibilities define the layer:
- Routing: maps a declared intent to exactly one canonical tool
- Namespace isolation: prevents two servers from exposing colliding names
- Schema normalization: presents one consistent input shape to the agent
- Access policy: enforces who can call what, regardless of what the agent decides
Now for the part nobody talks about: the request lifecycle is boring on purpose. Agent intent goes in. One canonical tool comes out. The result gets normalized on the way back. No guessing, no ambiguity, no retry storm.
Think about it this way. A prompt asks the model to be careful. A gateway makes carelessness impossible.
How to Route Without Killing Parallelism: Chains, Fan-Out, and the Router Layer
Gateways are not always the answer. Sometimes they are pure overhead. Here is the decision rule that keeps you honest.
Use a linear chain for 2 to 4 dependent steps. Step B needs step A's output, so sequence is mandatory. Use parallel fan-out for independent subtasks, because waiting on a router adds latency for zero benefit. Reach for gateway routing when server count grows and selection noise becomes the bottleneck.
This is where most people get stuck: they route everything through the gateway, including calls that never needed routing.
So apply the test. If two agents can plausibly call the same tool for different reasons, that tool belongs behind the gateway. If only one agent ever touches it, let it call directly and keep your latency budget intact.
State, Retries, and Guardrails: The Parts Agents Quietly Get Wrong
Agent memory is not state. It is a suggestion that disappears the moment a context window resets. When agent A hands off to agent B and the context is gone, your workflow silently restarts from zero.
The fix is unglamorous: move state into shared external storage. Handoffs then survive a reset because the state was never inside the agent to begin with.
Next, retries. Add exponential backoff, define a fallback per step, and decide fail-open versus fail-closed for each tool class. A read-only search can fail open. A payment or delete operation cannot.
And for high-risk actions, put the human checkpoint before the gateway executes, not after. An audit log of a mistake you already made is not a guardrail. It is a receipt.
Your First Gateway in One Afternoon: A Pragmatic Build Order
Start by pruning. Pick one tool per task type across all your servers, then register only what survives. Most teams find overlap they did not know existed.
Then write a routing manifest that maps intent to tool, and version it like code. When agent behavior changes, you want a diff to blame, not a vibe to argue about.
Finally, instrument two numbers before and after: tool-selection accuracy and retry rate. This is the 1-2 punch that ends the debate. If the gateway does not move those numbers, you built the wrong abstraction, and now you know in a week instead of a quarter.
Where This Breaks Next: Scaling the Gateway Past Ten Agents
A single gateway becomes a bottleneck once call volume and policy complexity outgrow one process. That is your signal to shard by domain: billing tools behind one gateway, content tools behind another.
Two things get harder as agent count grows, and both matter. Audit logging needs to be centralized even when routing is sharded, because the gateway is the only place that sees every call. Policy drift creeps in when each shard evolves its own rules, so the manifest has to stay the source of truth.
Here is the compounding payoff. A gateway turns tool access into a managed interface. Agents become swappable, because the contract lives in the gateway, not in the prompt.
Core takeaway: stop teaching agents to choose well, and start making the choice for them.
Your next 10 minutes: open your MCP server config, list every tool name, and circle the duplicates. That list is your gateway's first routing manifest.
Which approach are you running today, prompt-level guidance or a real routing layer? The tradeoffs are genuinely different at scale, and I would like to hear where yours broke first.